Social Computing × AI × Well-being
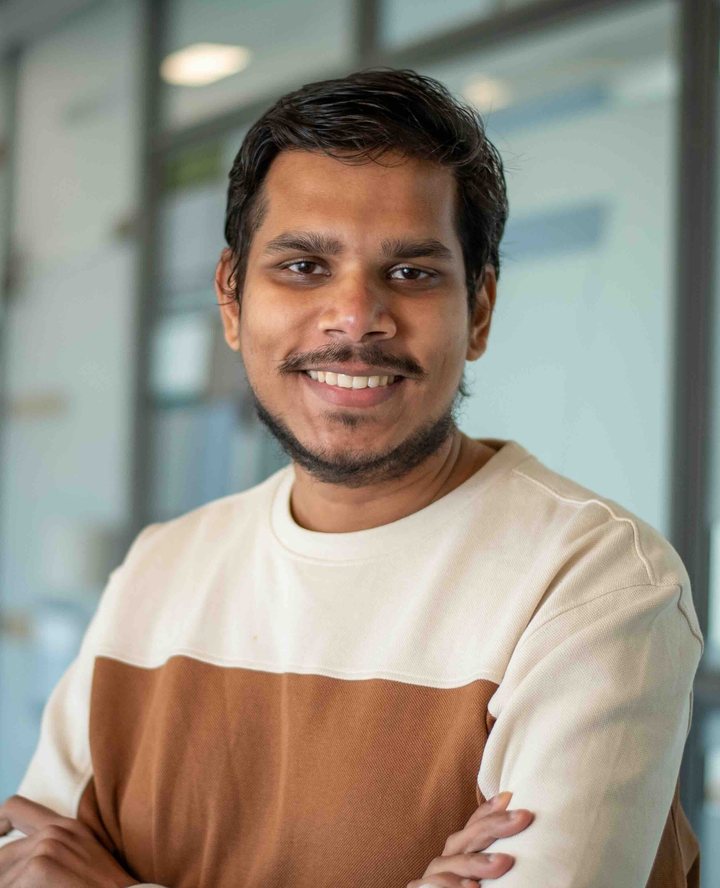
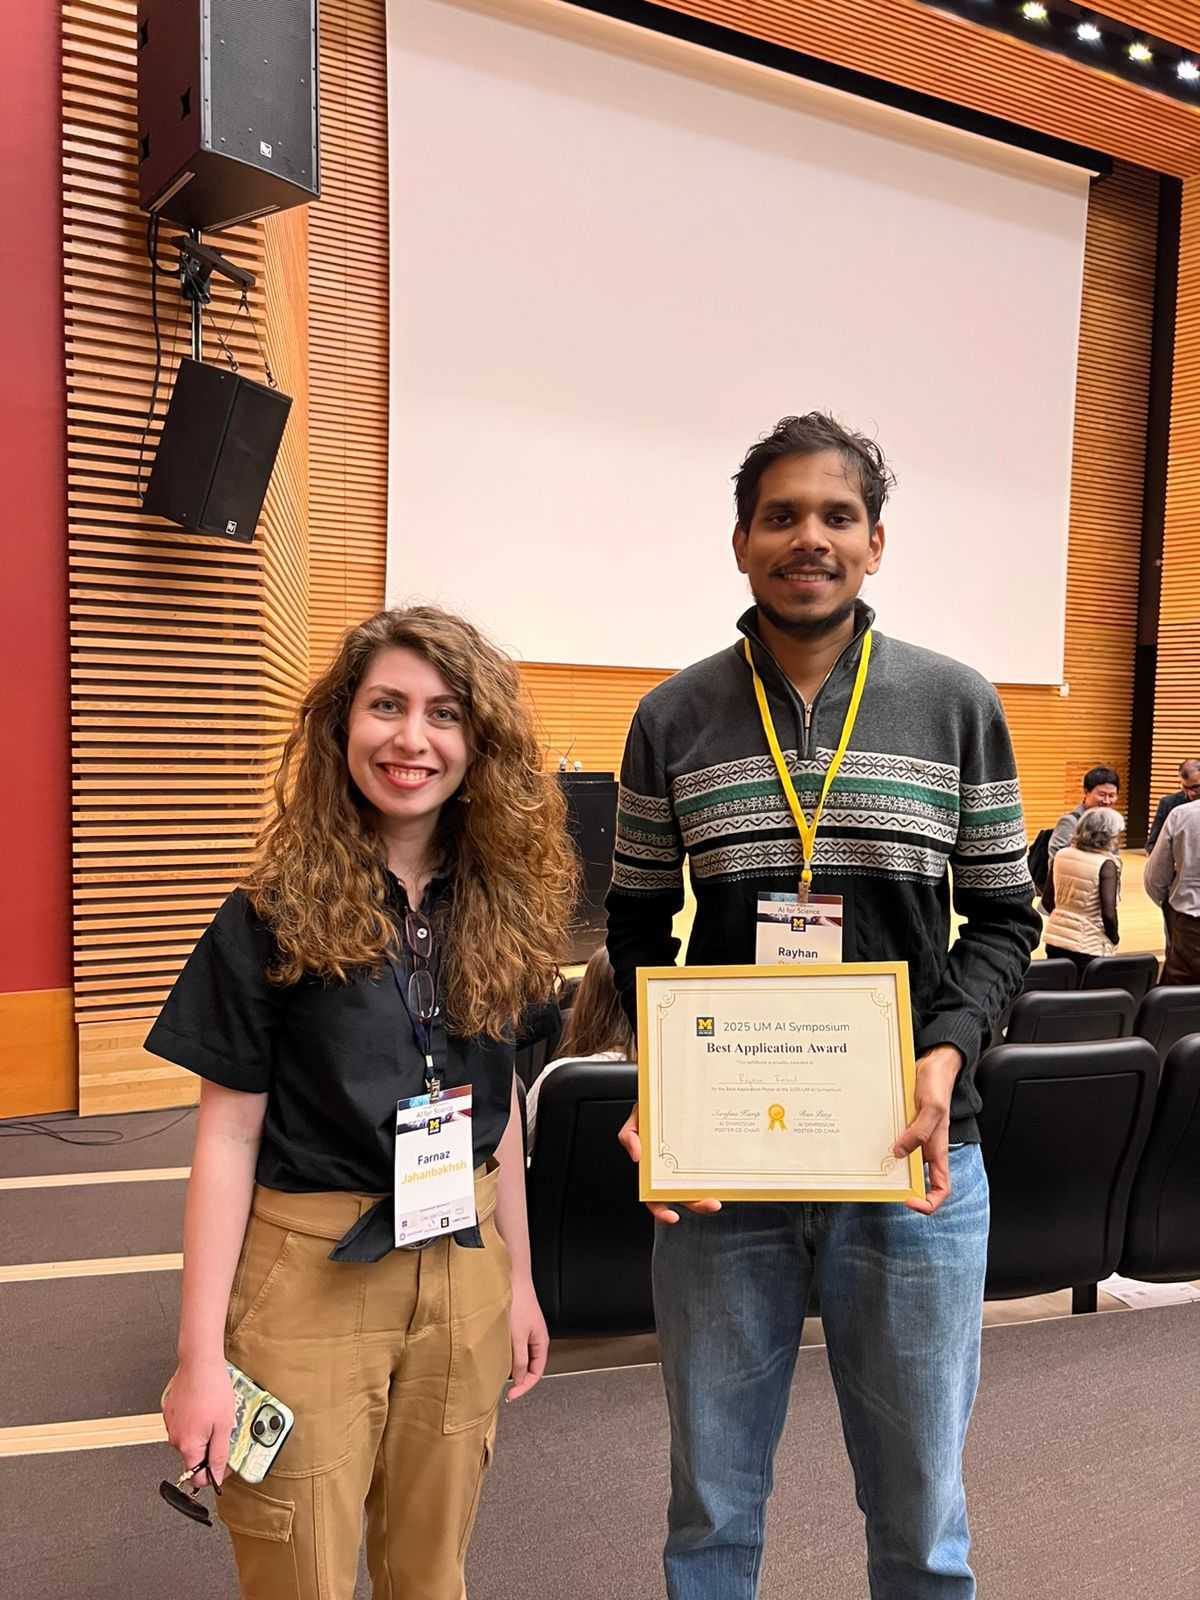
I’m a PhD student at Michigan. I’m in my third year, working with Farnaz Jahanbakhsh on AI for prosocial outcomes and safety. In January 2026 I passed candidacy. A month later, I had three minutes to explain my research. I won the Social Impact Engineering award. Most apps are optimized for time spent. I’m more interested in whether people come away better off. I worry that years of scrolling have changed how we concentrate. Quitting isn’t realistic for most of us; we go online for people and ideas. The trouble is what comes bundled with them. A useful video, for example, can be edited to be hard to stop watching. I’m exploring whether AI could keep the content but tone that down. The obvious sign of success would be watching less, but less isn’t always better. Someone might watch longer because they can finally follow something they care about, so minutes watched can’t be the only measure. I work on content moderation and AI that reads for us. Platforms decide what’s harmful for everyone at once, and usually remove the whole post. With DIY-MOD, people say what they don’t want to see, and AI changes just that part of the post. In our studies, we saw that hiding a detail can leave people imagining it. Enough context, or a benign replacement, could help them move on. More on the project page. When an assistant reads the web for you, someone can try to influence what it reads. That’s a way to persuade you through your assistant. Who should catch that? Telling people to trust AI less just puts the burden back on them.
Before Michigan, I taught at BUET. I was an assistant professor. I became one around the same time as my PhD advisor. In Bangladesh, you can start teaching right after undergrad. I joined as a lecturer, became an assistant professor, and then went back to being a student. In fall 2026, I got to teach again, co-teaching graduate HCI at Michigan.
I also spent time at Microsoft , helping computers listen, partly by teaching them to look at people’s mouths.
It helps when people talk over each other.
Mouth movements can tell a model whose voice to keep.
Clear audio isn’t much help if it’s the wrong person. Here’s the paper.
I support Chelsea because of one game.
It was Everton away in December 2006, and we were behind.
Then Ballack hit this free-kick.
We went behind again. Lampard brought us level.
Then Drogba did this.
It finished Everton 2–3 Chelsea. I’ve been a fan ever since.
I may have misunderstood how often that was going to happen.
You should also meet one of my cool friends. Shwetha Rajaram makes great research diagrams. People sometimes mistake them for concept sketches. They’re actually systems she built. One is Privacy Equilibrium, a simulation toolkit for privacy around smartglasses. Your glasses might scan a room to help you get around. What about the people nearby? Someone next to you may not want to be recorded. Whose preferences win? Her toolkit lets researchers set those preferences and see what the glasses would be allowed to sense. More on her website. Álvaro Vega-Hidalgo uses AI to study animal communication. One project asks whether a model can recognize which monkey is calling. The monkeys are wild white-faced capuchins, and recordings are scarce, so the model borrows from birds and humans. Combining what both kinds of models learned helps it tell the monkeys apart. Then there’s the question of what the model is listening to. His toolbox lets experts mark parts of a call and listen to them separately. It then compares their selections with the parts that influenced the model. That shows whether the model relies on sounds experts find meaningful. More on his website.
Selected Publications
What If Moderation Didn’t Mean Suppression? A Case for Personalized Content Transformation
ACM CHI
🏅 Best Paper Honorable Mention🏆 Best Application of AI, Michigan AI Symposium
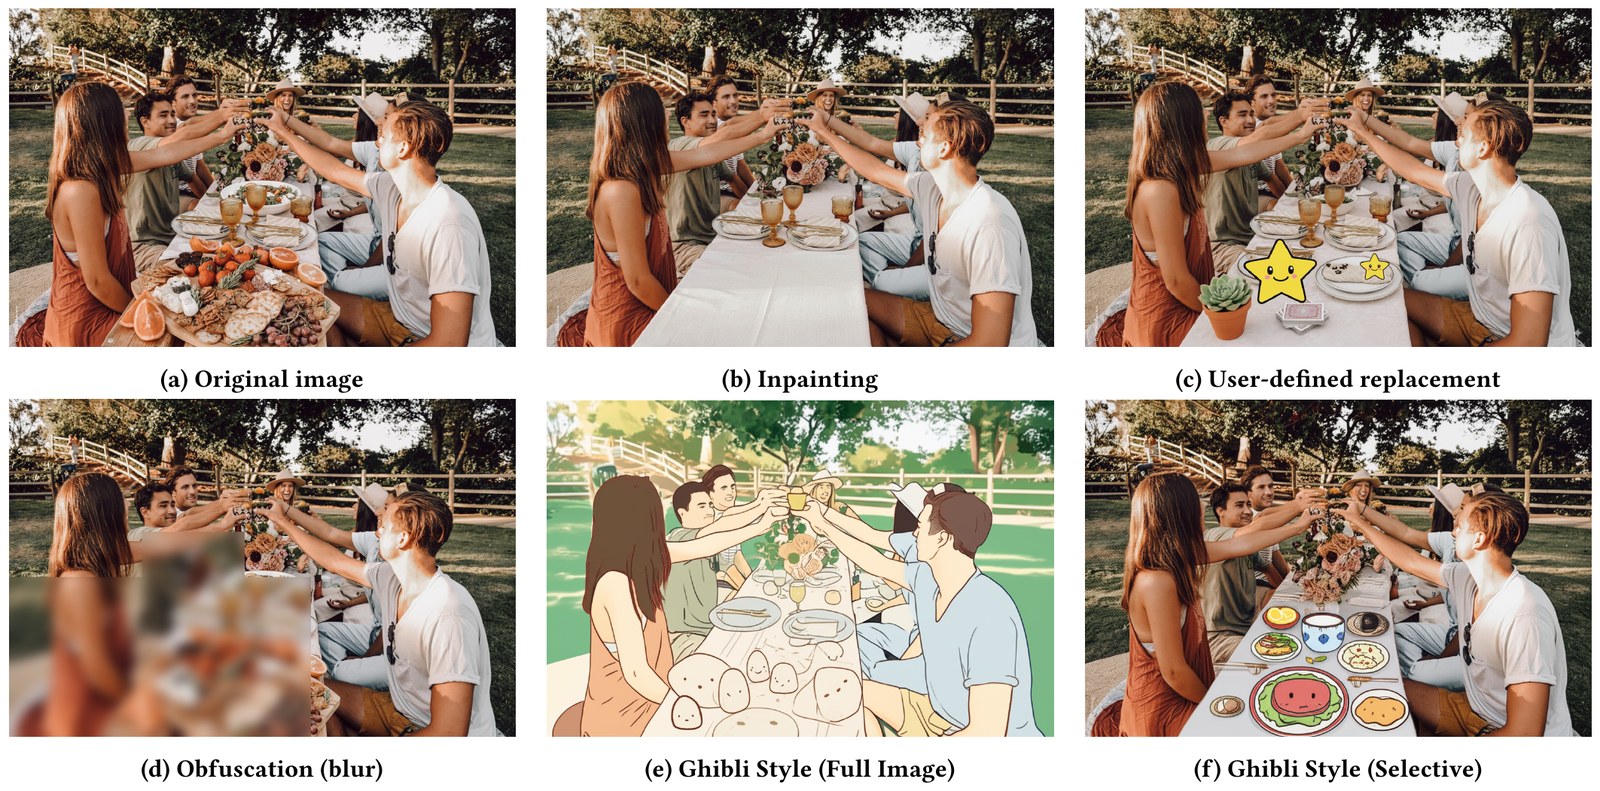
Also: Best Poster, Michigan HCAI Symposium
Adapting Personalized Speech Enhancement for Low-Latency Audio-Visual Target-Speaker Extraction
arXivUnder review at IEEE ICASSP
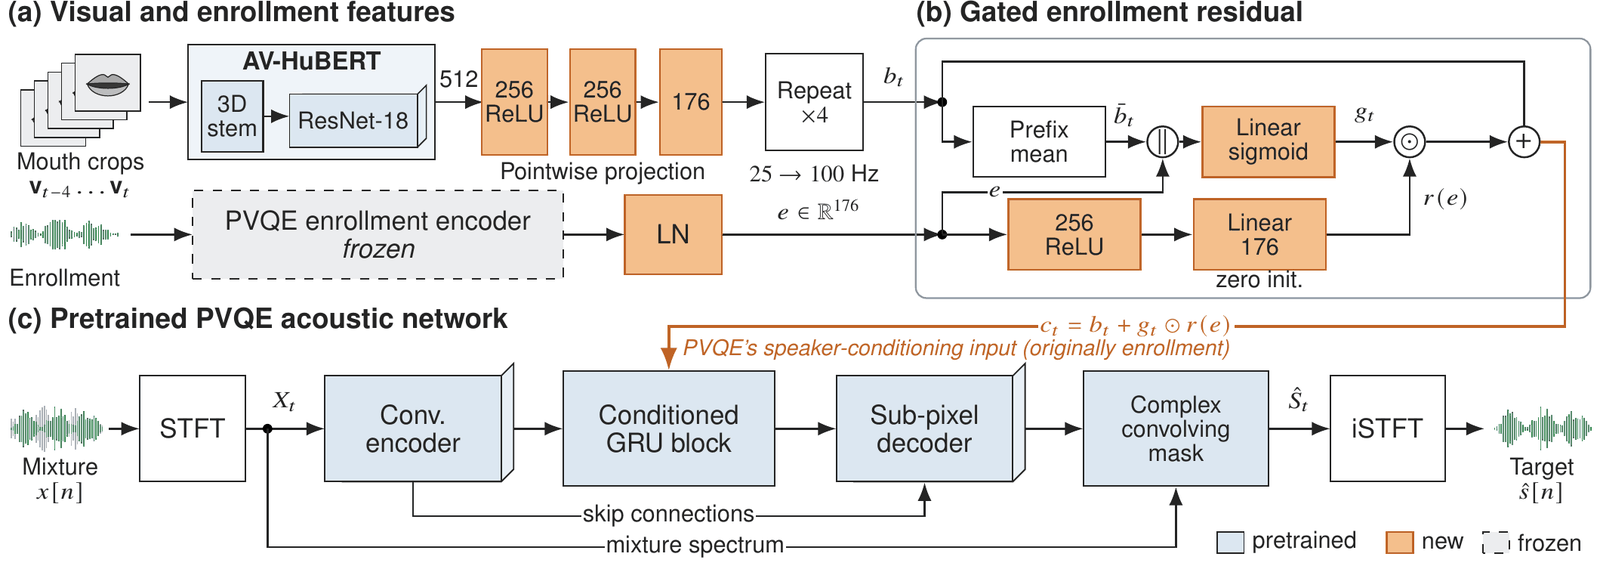
Two-speaker mix. The target, on video, is 9 dB quieter.
Speaker on video Other speaker
Audio only, the model follows the louder voice (−7.6 dB SI-SNRi). With the lip cue, it keeps the target (+13.8 dB). Clip from LRS3.
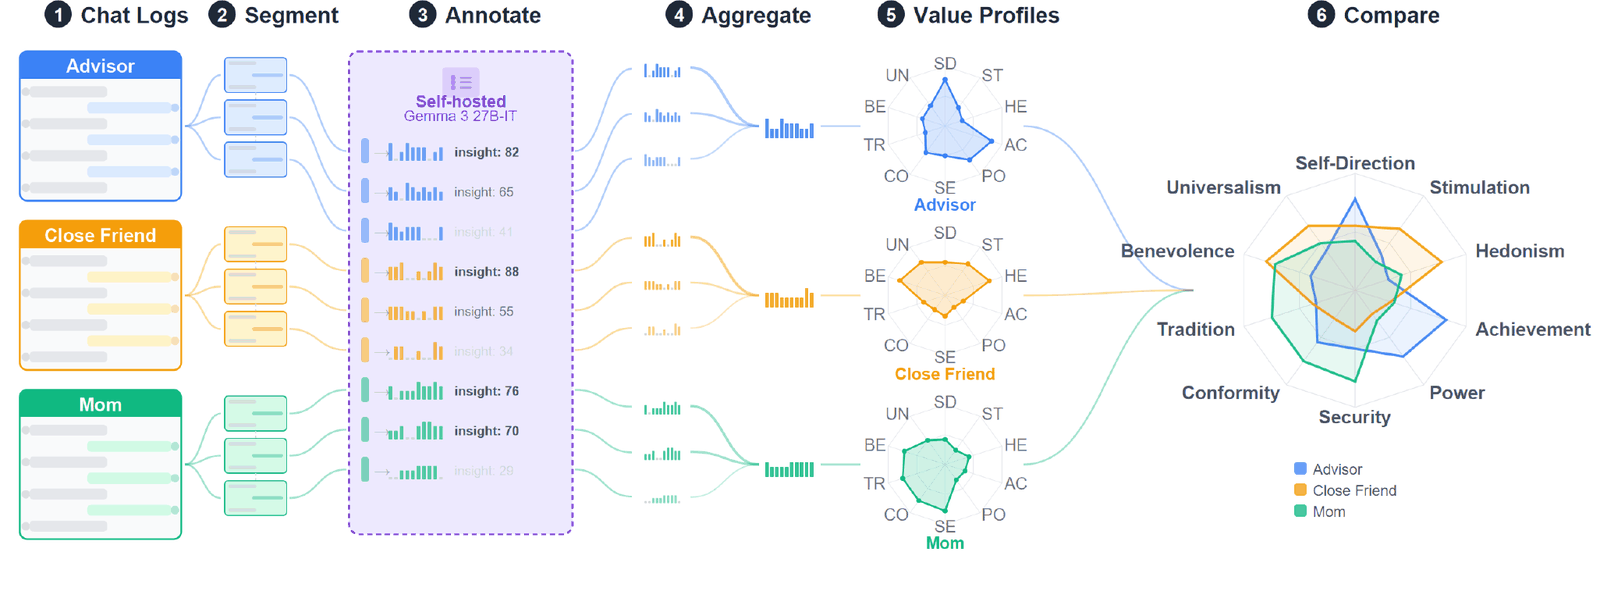
Value Faces: Surfacing How Self-Presentation Shifts Across Relationships
arXivUnder review at ACM CHI
See the complete list on Google Scholar.
Background
- 2026
Microsoft
PhD Research Intern, IC3 AI, with Ross Cutler. Low-latency audio-visual speaker extraction for live meetings.
- 2024–
University of Michigan
PhD in Computer Science & Engineering, Social Computing Lab.
CSE Departmental FellowshipMIDAS Empowering Research with AI Award
- 2023–24
National Center for AI, KSA
Research Engineer, AI in Education. Built KALEEM, a personalized tutoring platform with virtual tutors, deployed in schools.
- BS · MS
rayrash@umich.eduUpdated November 2026